ReassembleNet: Learnable Keypoints and Diffusion for 2D Fresco Reconstruction

1Istituto Italiano di Tecnologia (IIT) Genoa, Italy
2Università degli Studi di Genoa, Italy
3Durham University, England

Abstract

The task of reassembly is a significant challenge across multiple domains, including archaeology, genomics, and molecular docking, requiring the precise placement and orientation of elements to reconstruct an original structure.

In this work, we address key limitations in state-of-the-art Deep Learning methods for reassembly, namely i) scalability; ii) multimodality; and iii) real-world applicability: beyond square or simple geometric shapes, realistic and complex erosion, or other real-world problems. We propose ReassembleNet, a method that reduces complexity by representing each input piece as a set of contour keypoints and learning to select the most informative ones by Graph Neural Networks pooling inspired techniques.

ReassembleNet effectively lowers computational complexity while enabling the integration of features from multiple modalities, including both geometric and texture data. Further enhanced through pretraining on a semi-synthetic dataset. We then apply diffusion-based pose estimation to recover the original structure. We improve on prior methods by 55% and 86% for RMSE Rotation and Translation, respectively.
Video

Method

Method diagram
Framework of our proposed method. We begin by extracting keypoints from the input pieces, followed by computing global and local texture features alongside geometric features. Using the geometric features and keypoint coordinates, we then select the most relevant k keypoints. To model the reassembly process, we employ a Diffusion Probabilistic Model, formulating a Markov chain that gradually injects noise into the keypoints’ positions and orientations. At timestep t = 0, the pieces are correctly aligned, whereas at timestep t = T, their keypoints are randomly translated and rotated (note that for visualization purposes, we compute the average translation and rotation of keypoints within each piece at every step in the chain). At each timestep t, our attention module processes the keypoints—incorporating their coordinates, orientations, and extracted features—to predict a less noisy version of their positions and orientations, iteratively refining them toward the correct configuration.

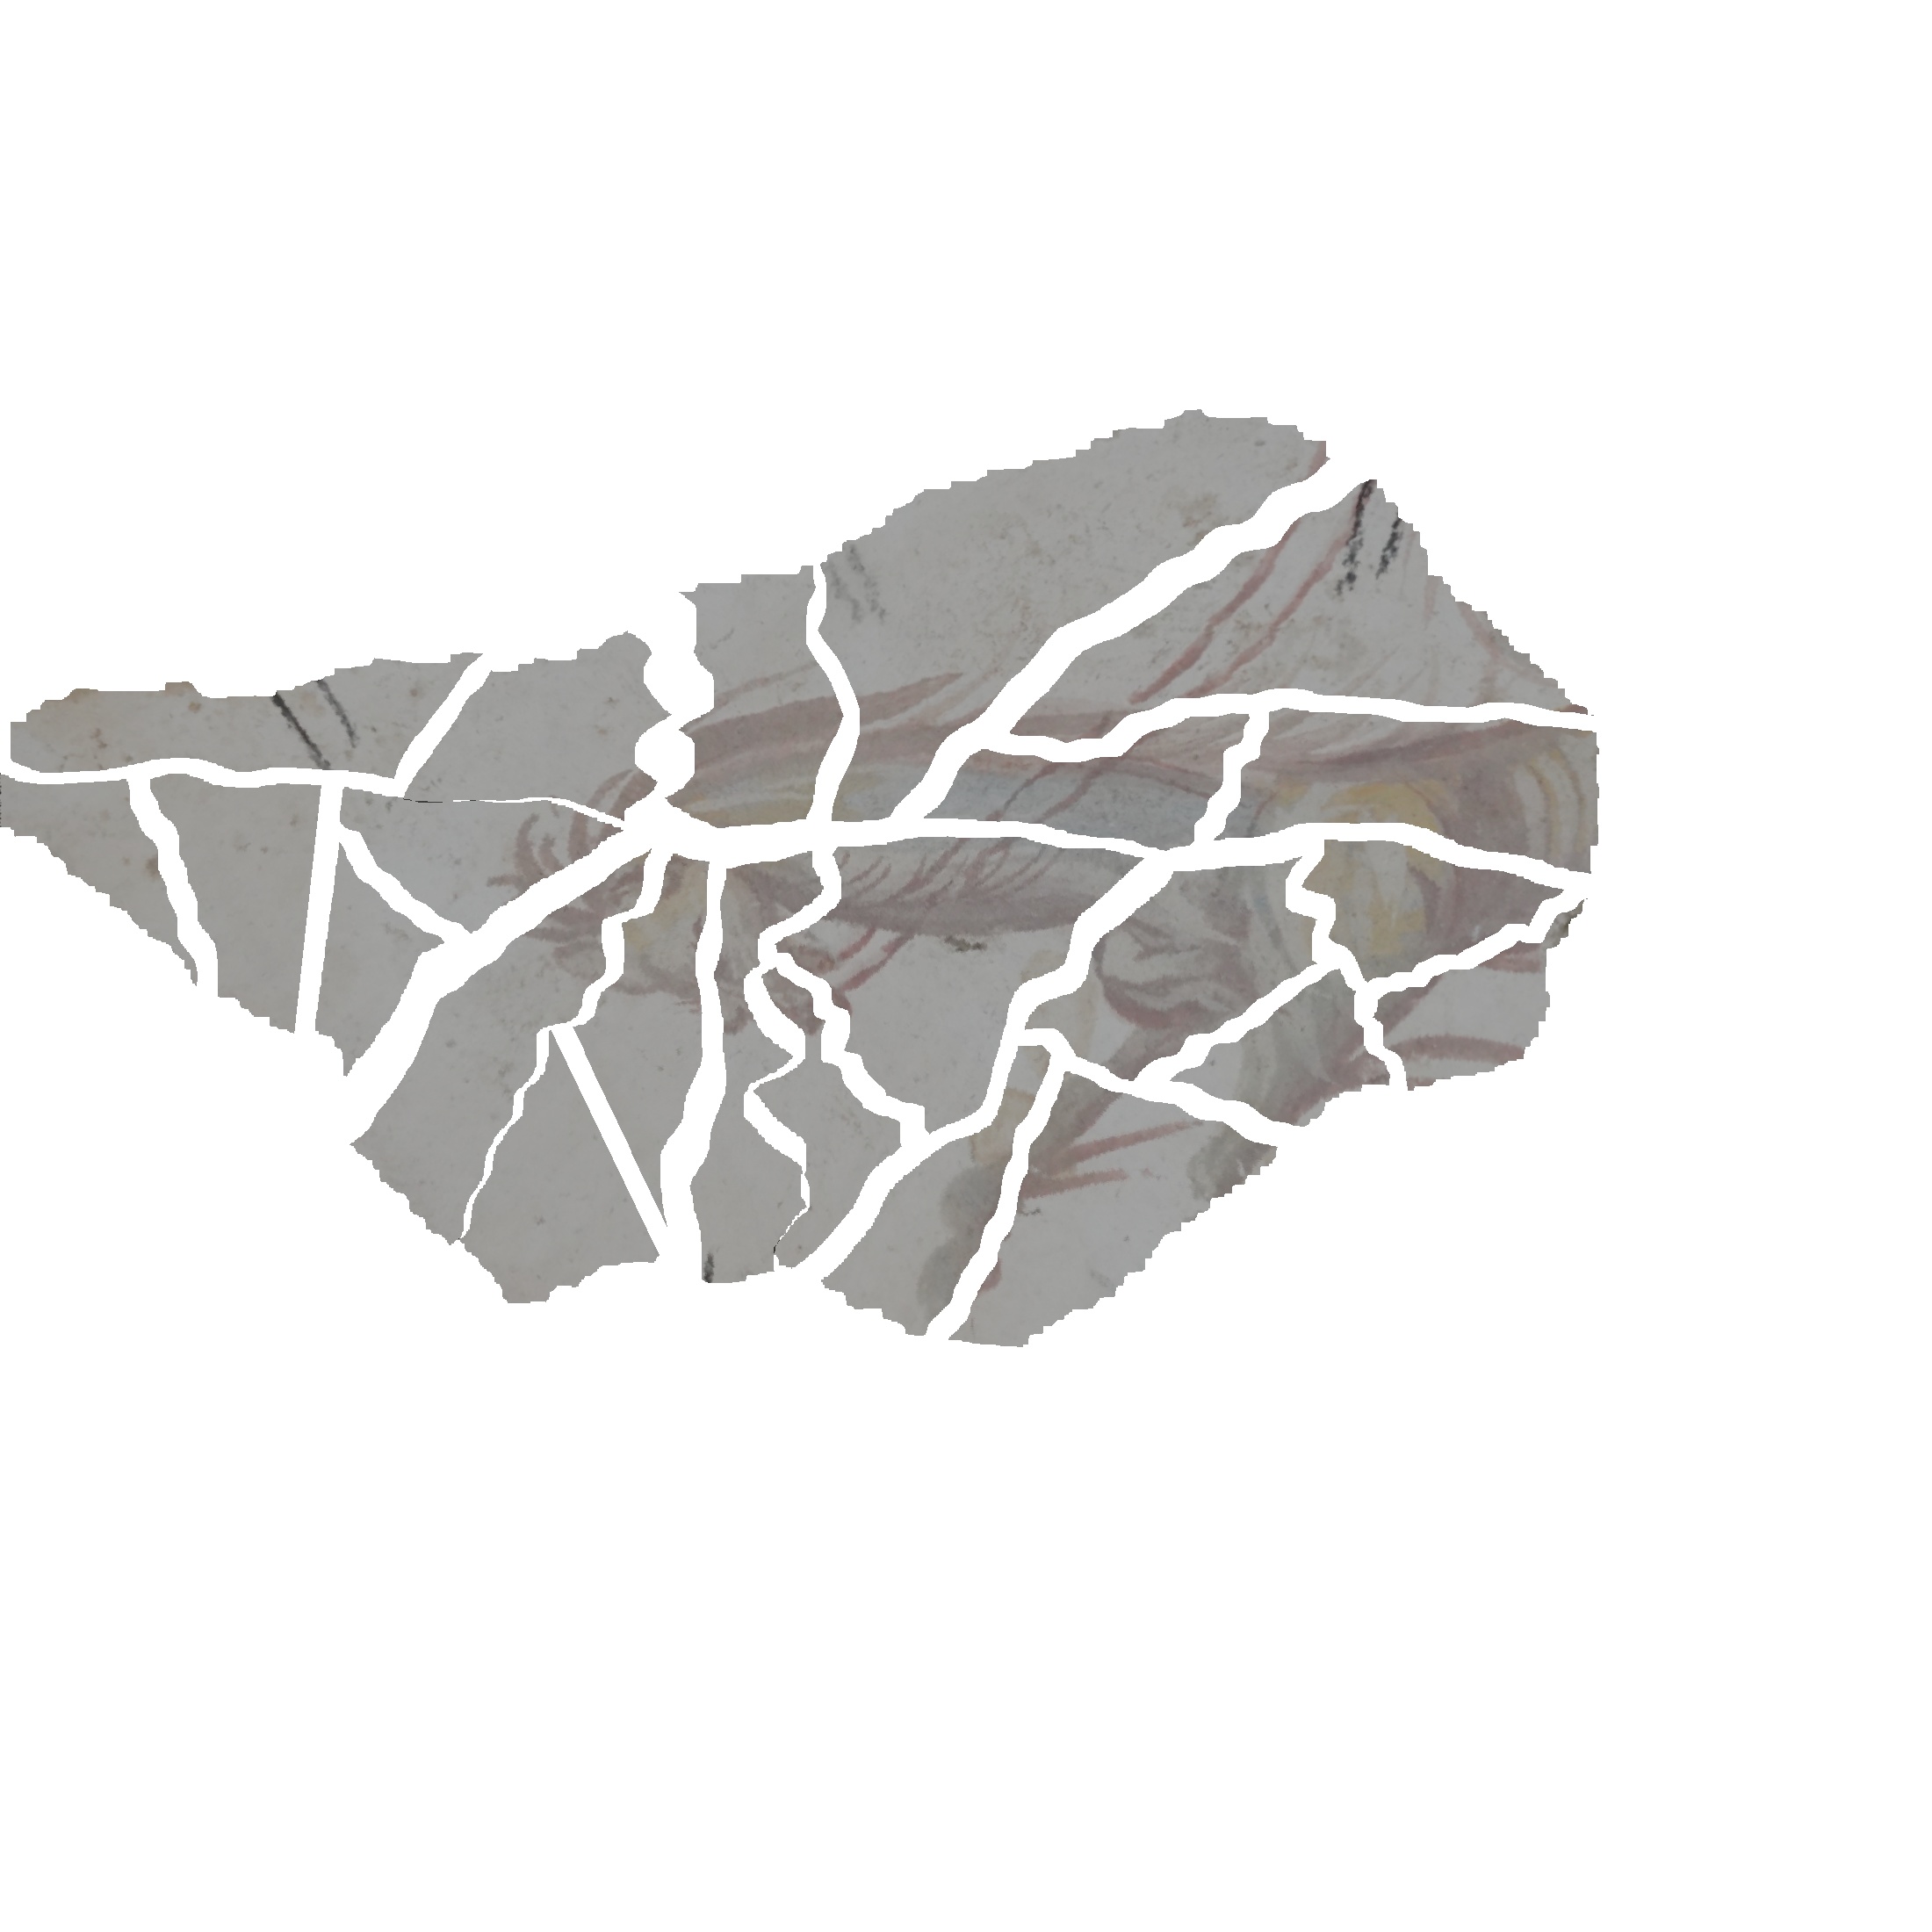
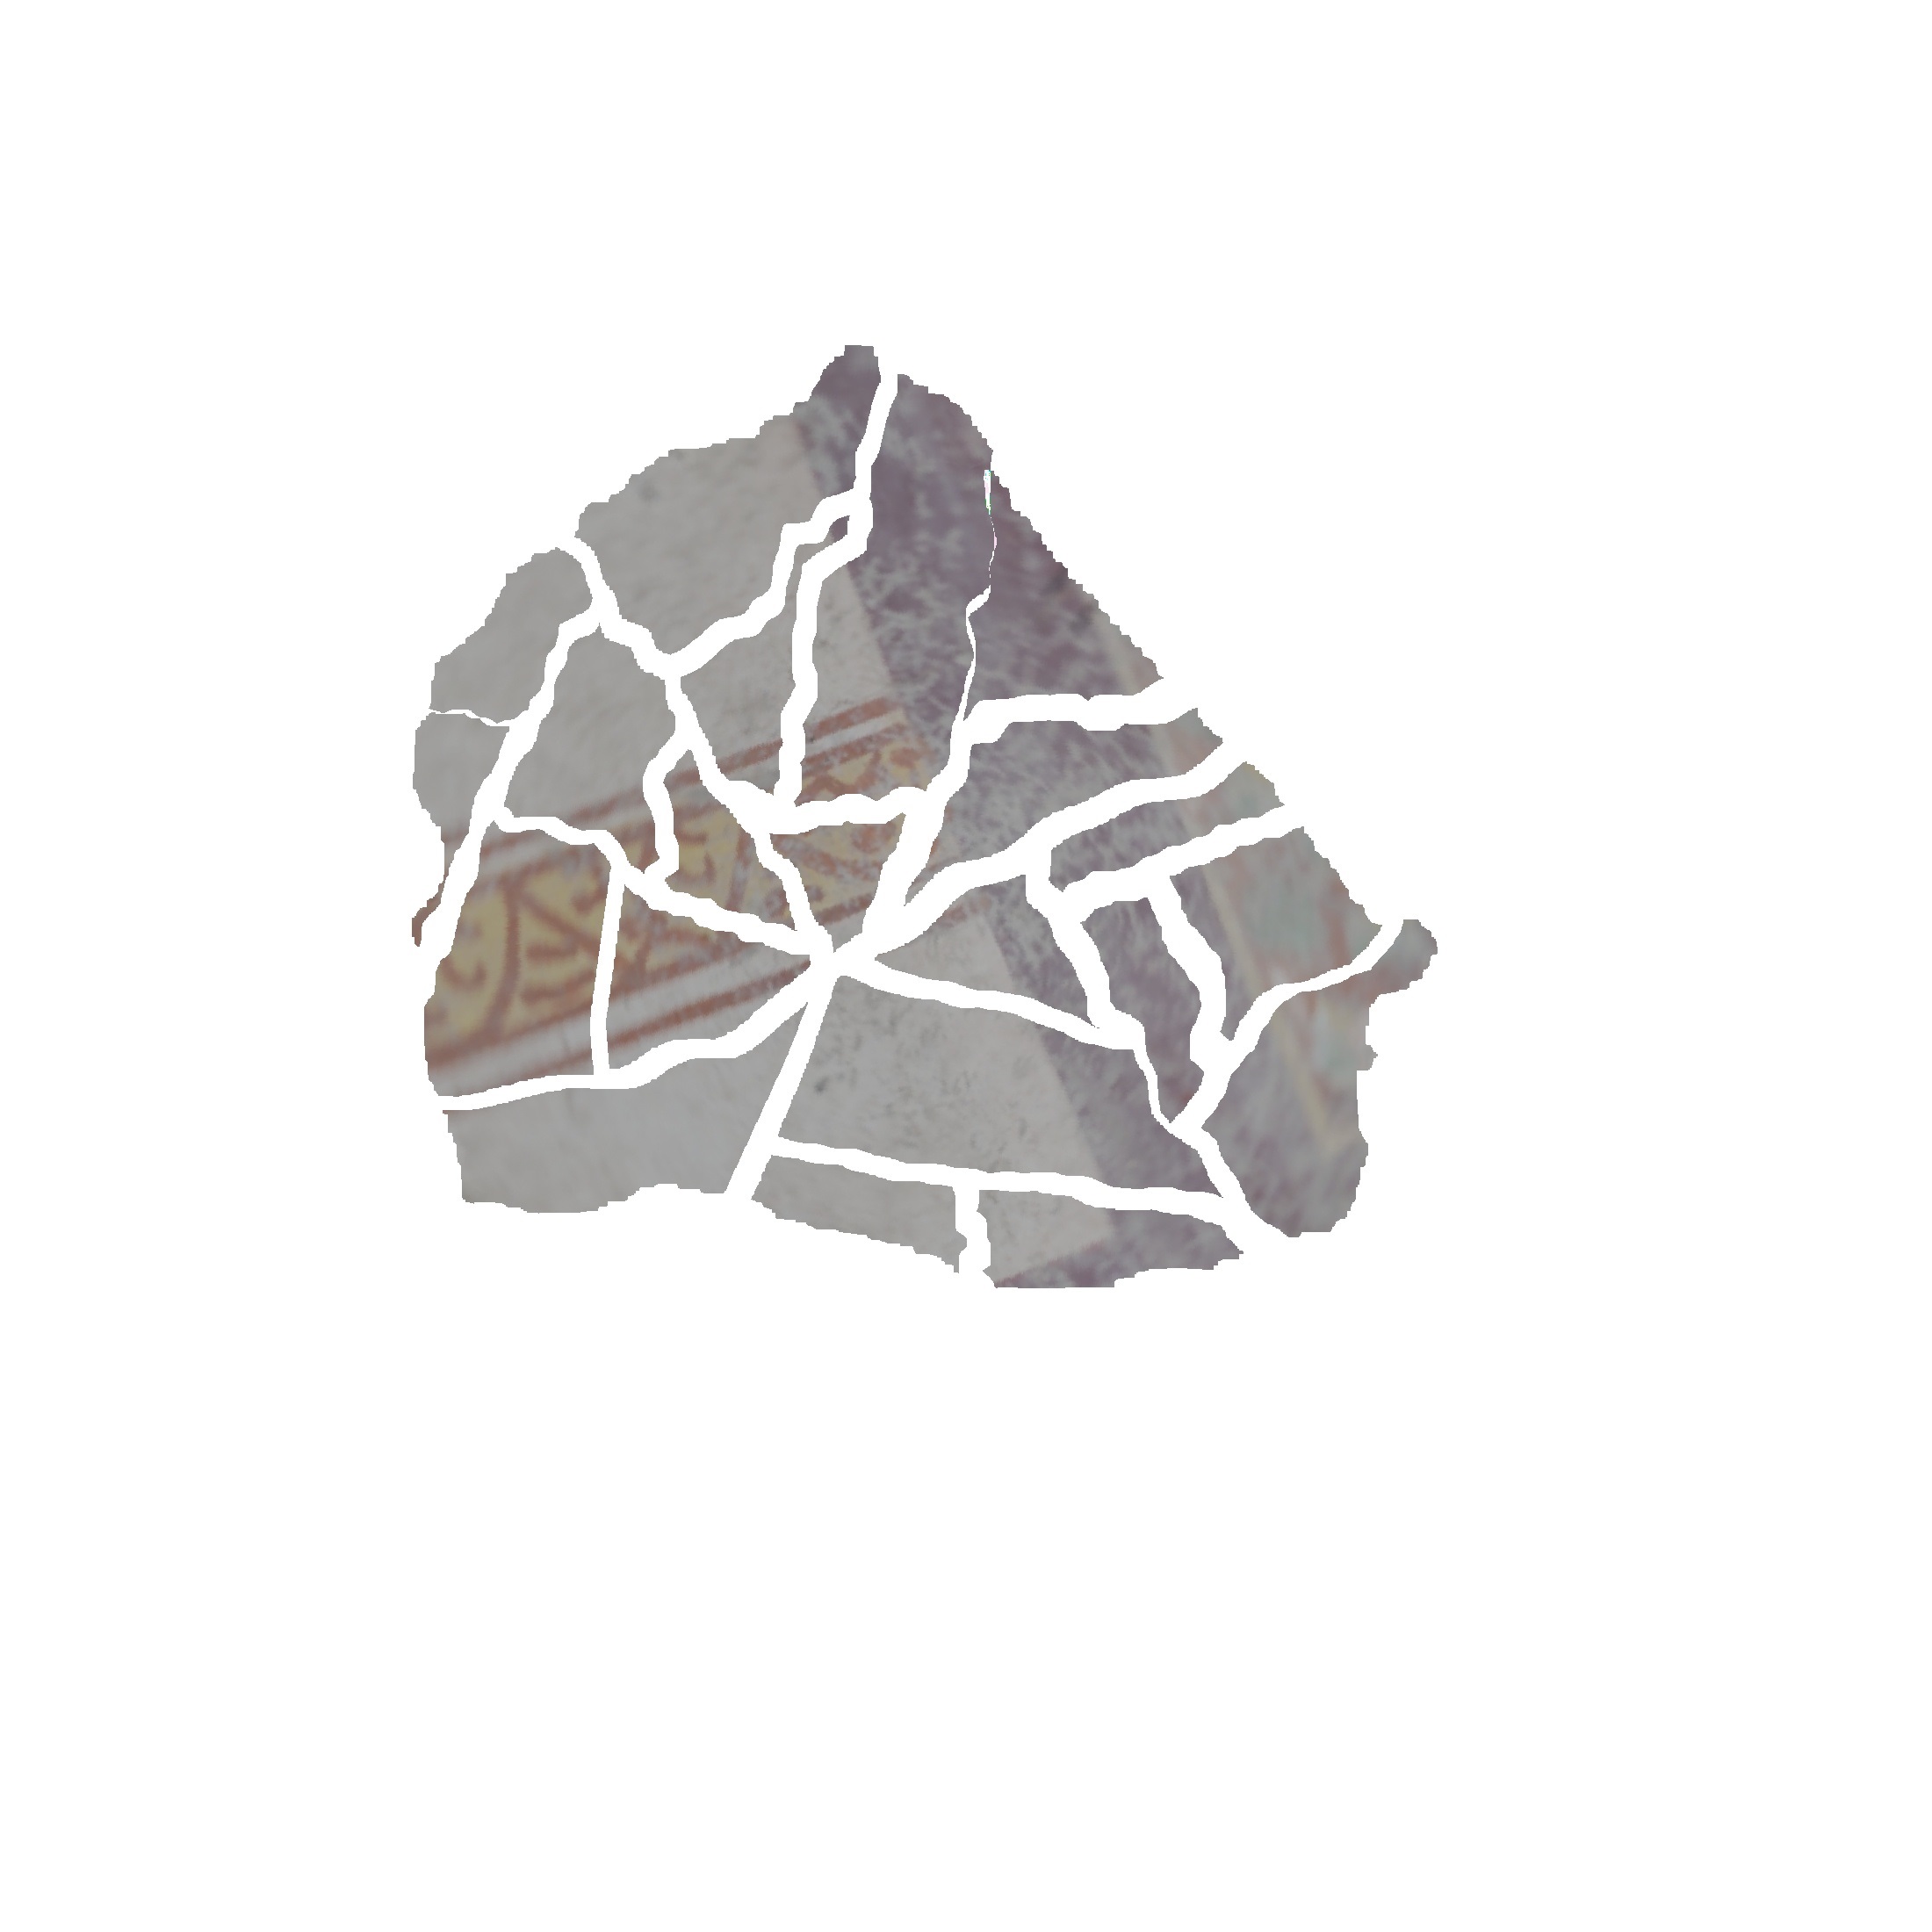
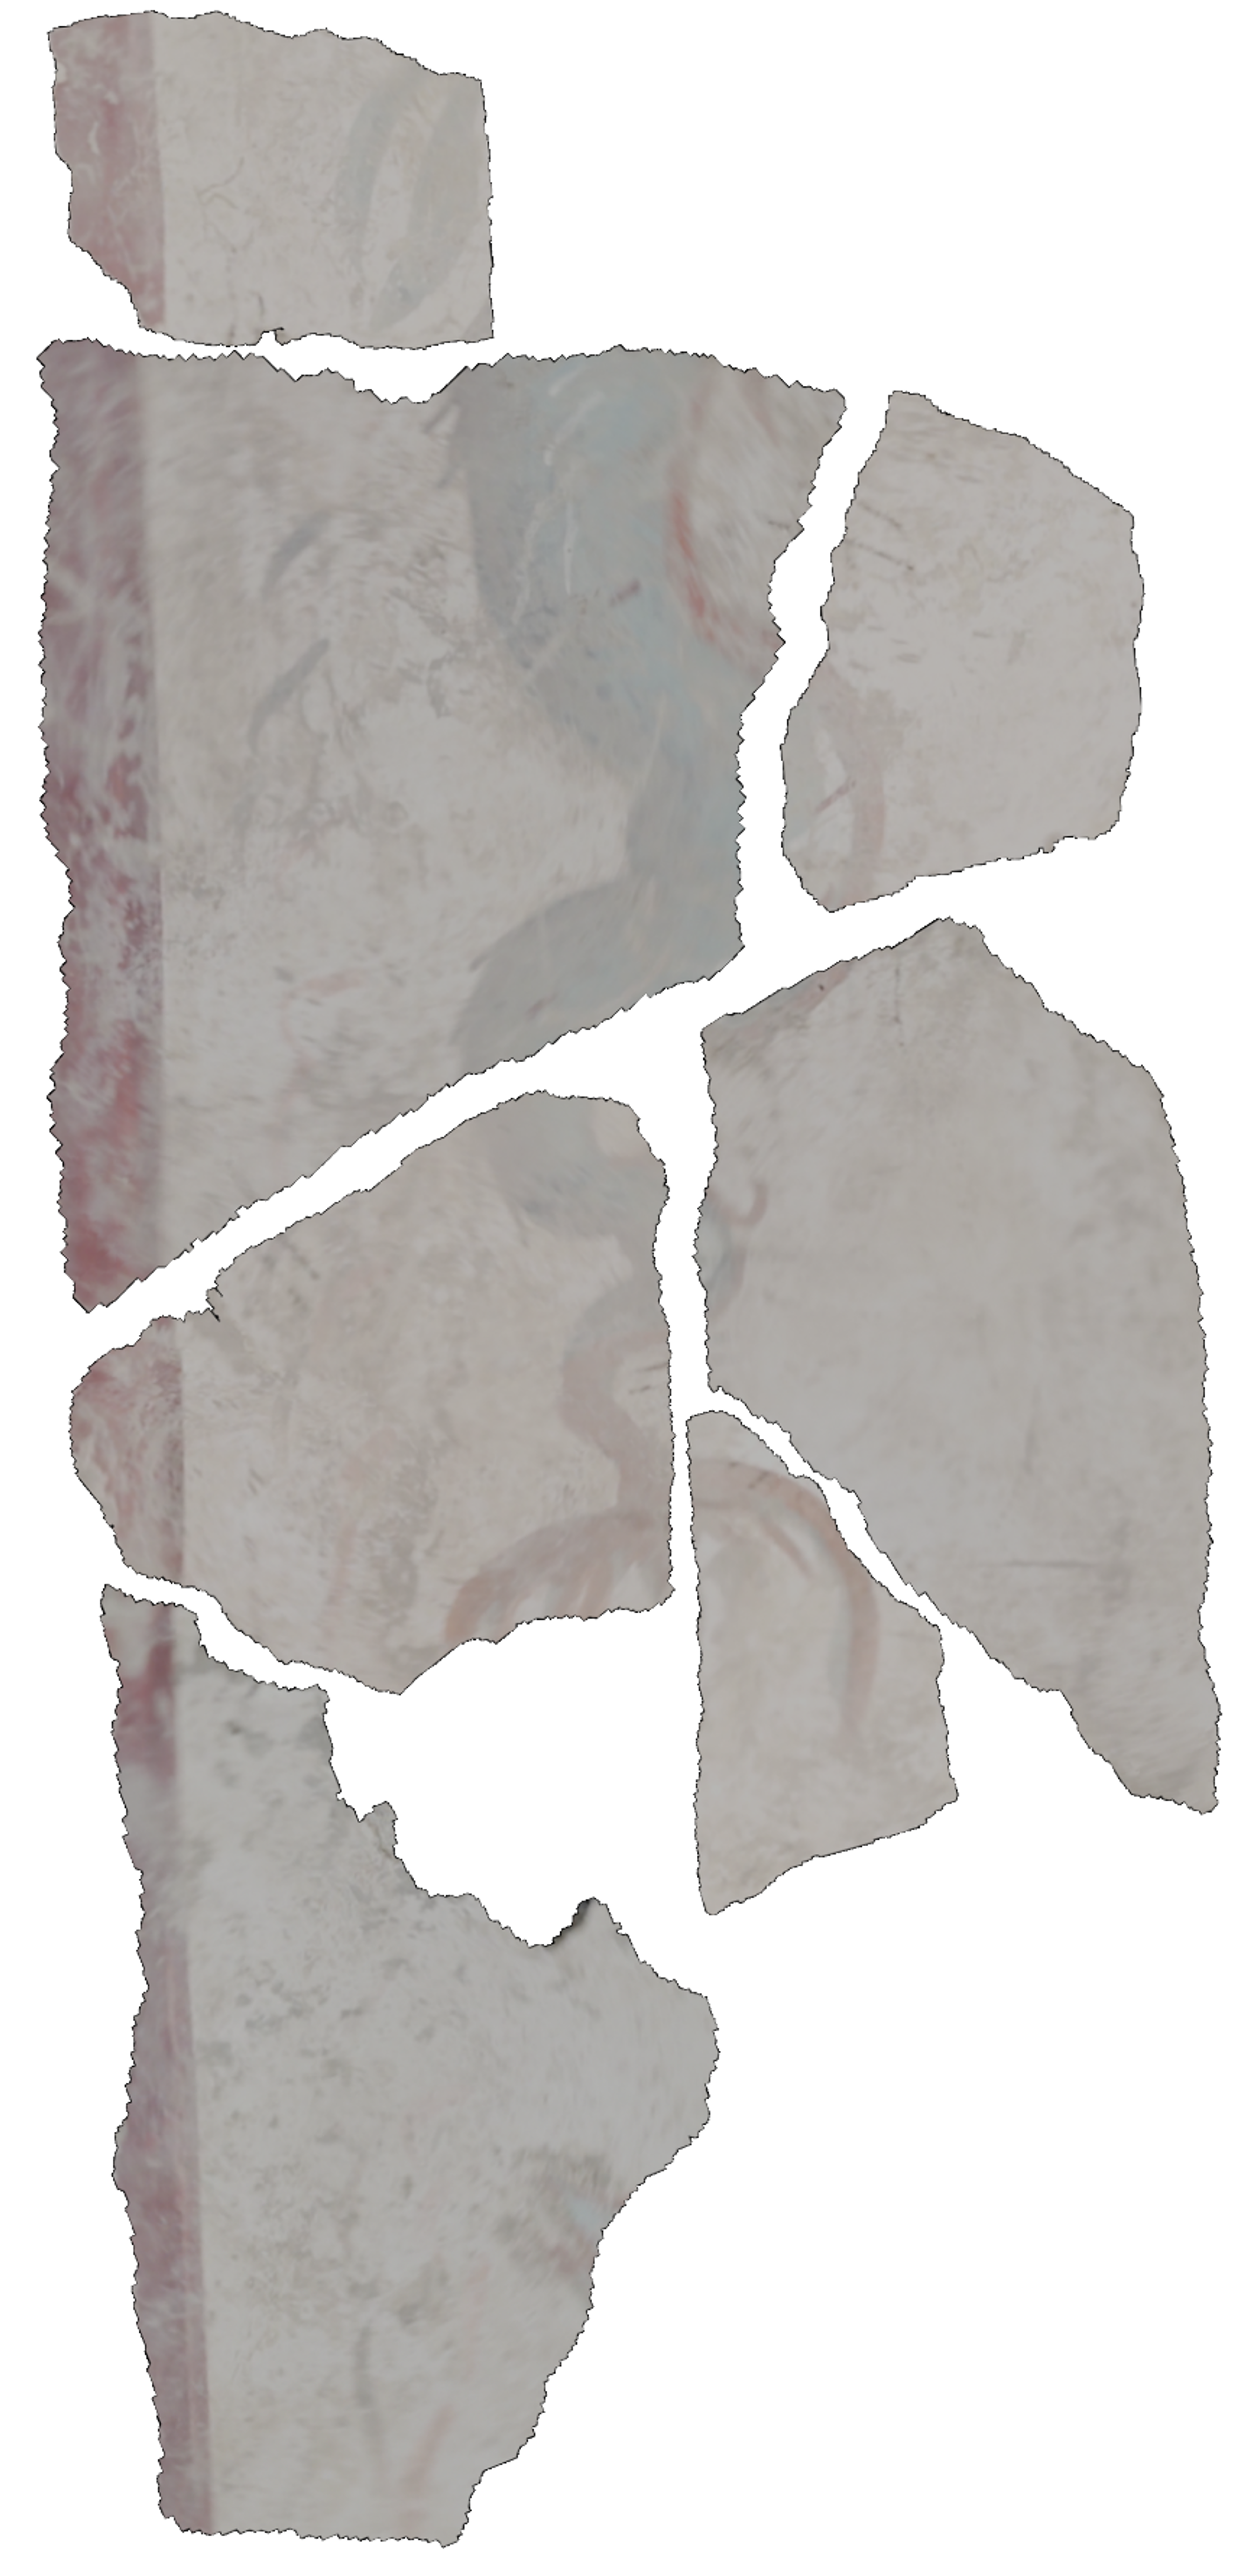
A preview of the Semi-Synthetic Dataset

RePAIR
Semi-synthetic
Semi-synthetic

Results

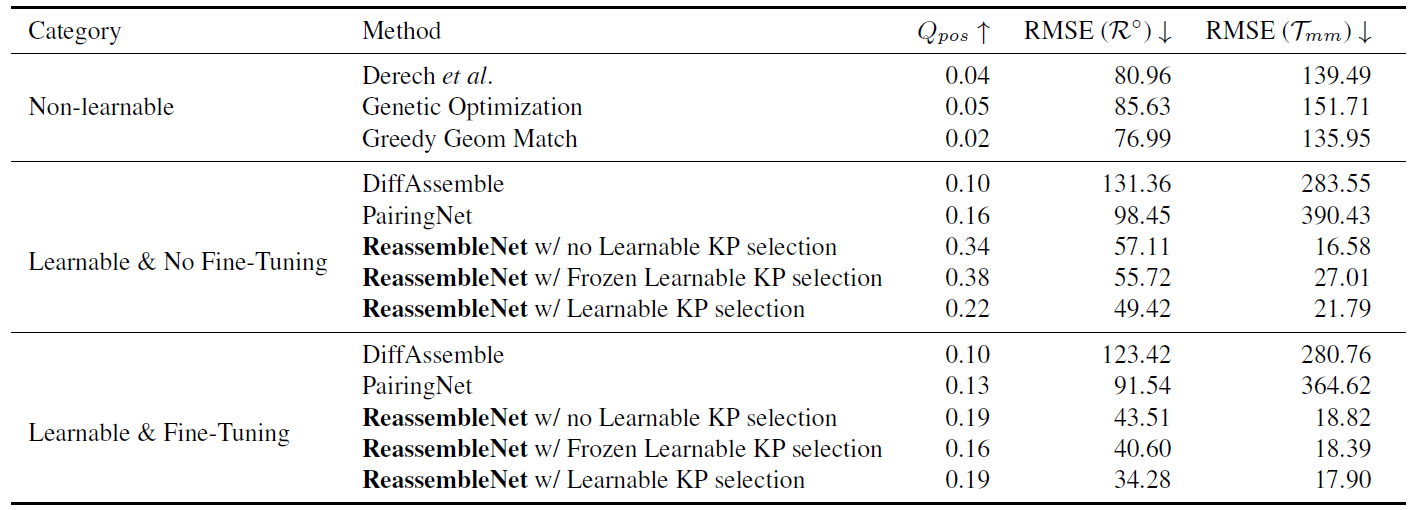
Results Table
Results on RePAIR dataset using Qpos for groundtruth overlap, Root Mean Square Area (RMSE), in terms of rotation (ℜ°) and translation (mm).

BibTeX

@article{islam2025reassemblenet,
  title={ReassembleNet: Learnable Keypoints and Diffusion for 2D Fresco Reconstruction},
  author={Islam, Adeela and Fiorini, Stefano and James, Stuart and Morerio, Pietro and Del Bue, Alessio},
  booktitle = {International Conference on Computer Vision (ICCV)}
  year = {2025}
}